Pablo Posted March 9 Posted March 9 Every once in a while, I do a check to see how well Pablo rankings for a given week do at predicting outcomes of matches in the following week. It's useful data to know (usually it comes in at about 75%), but it's hard to interpret because that depends on a lot of factors, like how close the actual matches are and other stuff. It is what it is. However, come conference tournaments, we actually have the opportunity for comparison because we have seeding. Despite the issues that happened with the Big Ten pre-seeding, in the end the seeds were adjusted and so that is all well and done. What I've done now is to compare at how often the better seeded wrestler (higher seed? Lower seed? what's the correct description?) won in the conference tournament vs how many times the higher rated wrestler in Pablo won. Pretty good data set, with more than 1300 matches (note that I don't count matches that don't end properly, so no byes, forfeits, injury defaults, DQs, etc) In those matches, the higher rated wrestler in Pablo won 77.8% of the time. I also went through all the brackets and logged the results based on seeds. This was all done counting outcomes manually, so I may have missed something here or there, but after doing that, I got that the better seeded wrestler won 75% of the time. The difference isn't huge, but over 1300 matches, that difference is significant. It's almost 40 more matches correctly predicted using Pablo than by the seeds. If you focus only on the top, you will see some problems with Pablo, like Bouzakis rated higher than Lilledahl but seeding had correct, but that is taken into account in the assessment. Should tournaments just be using Pablo for seeding? I won't say that, but hey, the could do worse...and they do. Maybe do the seeding for the top 4 and let Pablo handle the rest? FWIW, I don't have the breakdowns at the conference/bracket position level for Pablo, but I can tell you from a seeding standpoint, seeds do a lot better in the championship side of the bracket (79%) than on the consolation side (69%). A lot more upsets on the consolation side of the bracket. From a seeding perspective, the Pac 12 (83%) and Ivy (80%) had the most accurate seeding. Then again, those were smaller tournaments, so not near as many wrestlers to seed. At the other end was the SoCon, where only 66% of the better seeded wrestlers won. All the other conferences were pretty close to that 75% mark. The tl;dr summary: Pablo does as good of a job at assessing wrestlers (if not better) as the people seeding the brackets. To be fair, Pablo doesn't have to worry about crap like "doesn't have enough matches to qualify for RPI" and the like, although it also doesn't have the ability to rate wrestlers who have no matches at their conference tournament weight (there are a few, but not Gabe Arnold - he had a few matches at 197)
Pablo Posted March 9 Author Posted March 9 Not all seeding was a problem, though. For example, at 184 in the Big Ten, the better seeded wrestler won 27 out of 28 matches! That includes the matches for 9th (or was it 11th?). That is incredible. In terms of weight classes, though, 197 was the best seeded, with 78.2% correct. 184 came in at 77.7%. At the other end, 157 was the hardest weight class to seed, only 71.7%, and 125 was 72.6%. 165 was 73.3% and everyone else was pretty close to 75.
Pablo Posted March 9 Author Posted March 9 (edited) Unrelated to seeding and to Pablo ratings. I have looked at winning pct vs Pablo rating difference. The premise of Pablo ratings is that when guys are close in quality, the chance of either winning gets closer to 50/50. Basically, if you took Jesse Mendez and duplicated him and had him wrestle his duplicate, someone would win, but who would win would basically be 50/50. At the other end, if you took him and had him wrestle some random middle schooler, the probablity of him winning is basically 100% (there is a non-zero probability that a ceiling beam could fall and cause an injury default). Most D1 wrestlers are somewhere in-between. The plot below shows the winning percentage for the higher rated wrestler as a function of that rating difference (these are based on last week's ratings). As expected, as the rating difference goes to 0, the winning percentage goes to 50/50. As the rating difference gets bigger, the winning percentage increases and then asymptotes toward 100%. I can tell you that when the difference was greater than 3300, the higher rated wrestler always won (interestingly, the biggest upset of the weekend was in the EIWA at 133, where 150th ranked Treshaun Tecson beat #62 Mason Leiphart of Franklin&Marshall, a rating difference of more than 3200; that was the only upset where the rating difference was >2650) Edited March 9 by Pablo
Pablo Posted March 9 Author Posted March 9 There is more to it, though. That winning percentage vs rating curve has an analytical relationship. If you remember your stats class, it has the shape of a standard integrated normal distribution. If you don't remember your stats class, what you can do is to look how far the rating difference (in standard deviations) is from the mean (in this case 0) and convert it to a probabilty (statistical programs have this information built in; in Excel you use normsdist to convert rating difference to probability, or normsinv to convert probability to rating difference). The way Pablo is designed is that it should be linear with respect to that transformed probability. Details of how that gets implemented are available upon request. But the key is the plot of the transformation vs rating difference. Indeed, this is a pretty darn good linear relationship (r^2=0.988). The other feature of this plot is the slope, which is 0.0007 or something like that. The higher the slope, the more senstive the winning probablity is to the difference. In principle, the slope would nominally be 0.0005, so it's about 40% higher. I can tell you that is really good. Earlier in the season that slope will be more like 0.00035 (a slope of 0 would mean that the every match has a 50/50 outcome regardless of the rating difference). In the end, Pablo is cooking along pretty well now. I've started working on pre-nationals rankings and will update when I know more. 1
Pablo Posted March 10 Author Posted March 10 58 minutes ago, DeezyDoesIt said: This is great work. Thanks! Thanks. The challenge is that the dataset is so massive and the calculation takes so long to do that I really can't do regular testing that I'd like to do. But I had two weeks before the conference tournaments to get things clean and in order. It will also be great for getting match pairs to use to analyze predictablity of outcomes.
ceraIOI Posted March 11 Posted March 11 have you posted anywhere how Pablo exactly works/how you developed it? seems like the magic pretty solid numbers based rating tool of our dreams
ionel Posted March 11 Posted March 11 2 minutes ago, ceraIOI said: have you posted anywhere how Pablo exactly works/how you developed it? seems like the magic pretty solid numbers based rating tool of our dreams Pablo knows how Pablo works just ask Pablo. Good stuff! .
Nevaeh Lavarias Pearl City High School, Hawaii Class of 2027 Committed to Kent State Projected Weight: 124
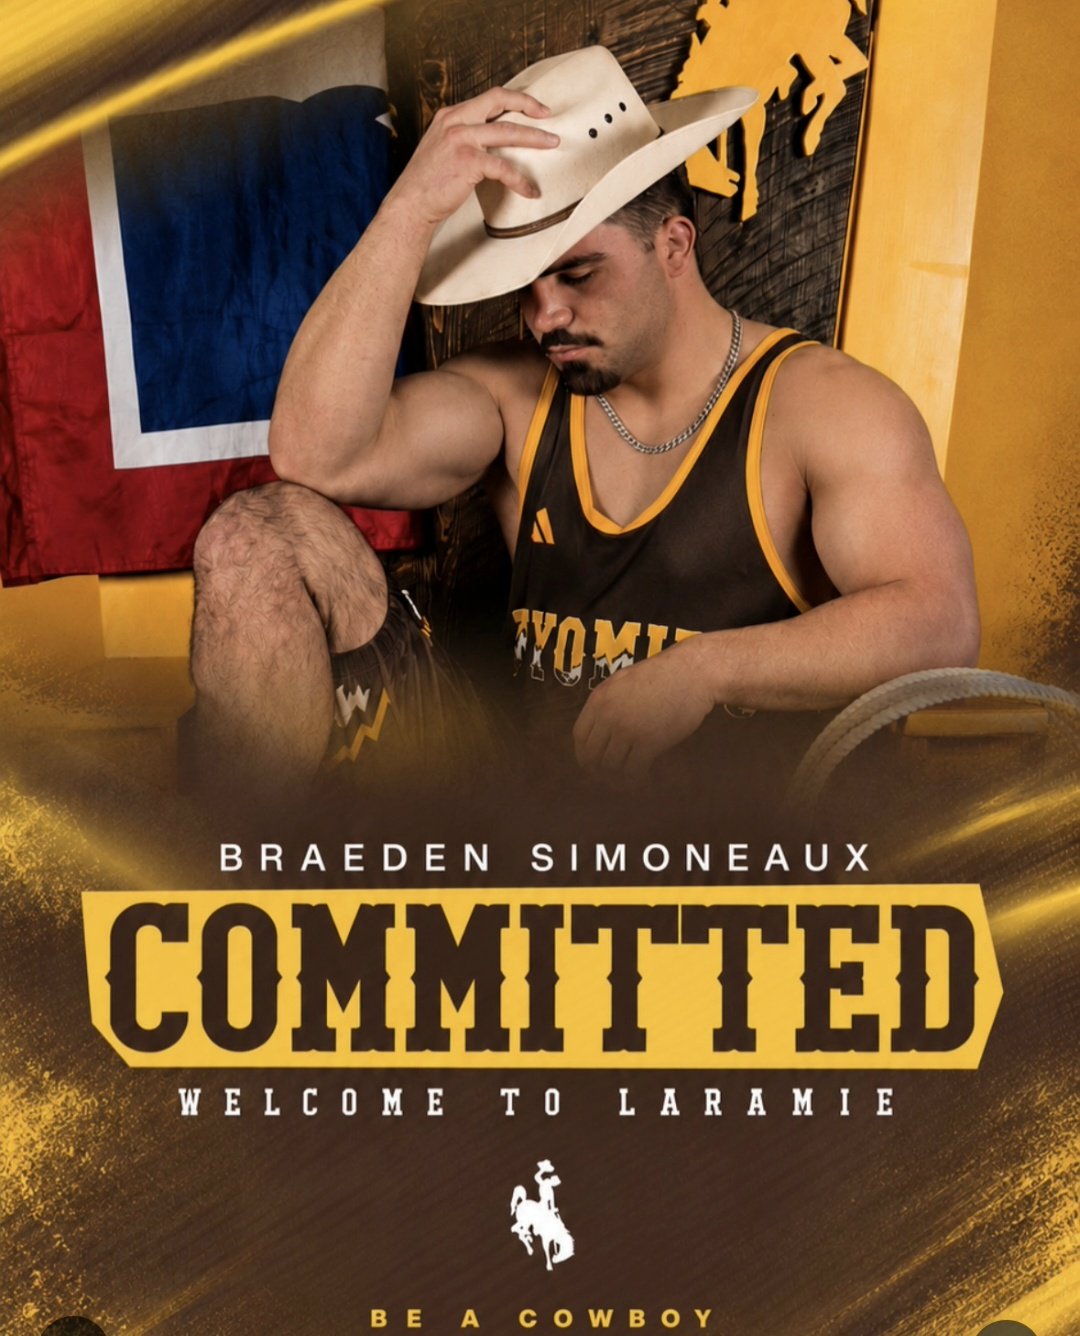
Braeden Simoneaux New York Military Academy, Louisiana Class of 2027 Committed to Wyoming Projected Weight: 184, 197


Recommended Posts
Create an account or sign in to comment
You need to be a member in order to leave a comment
Create an account
Sign up for a new account in our community. It's easy!
Register a new accountSign in
Already have an account? Sign in here.
Sign In Now